
Amazon Book Ranking Factors
Separate published guidance, observed results and untested hypotheses before choosing a publishing change.
An evidence register and a repair order, not invented algorithm weights or guaranteed positions.
A useful factor list states the evidence and its limits
Separate search placement, sales rank, metadata rules and reader-experience hypotheses. They do not form one publicly disclosed weighted checklist.
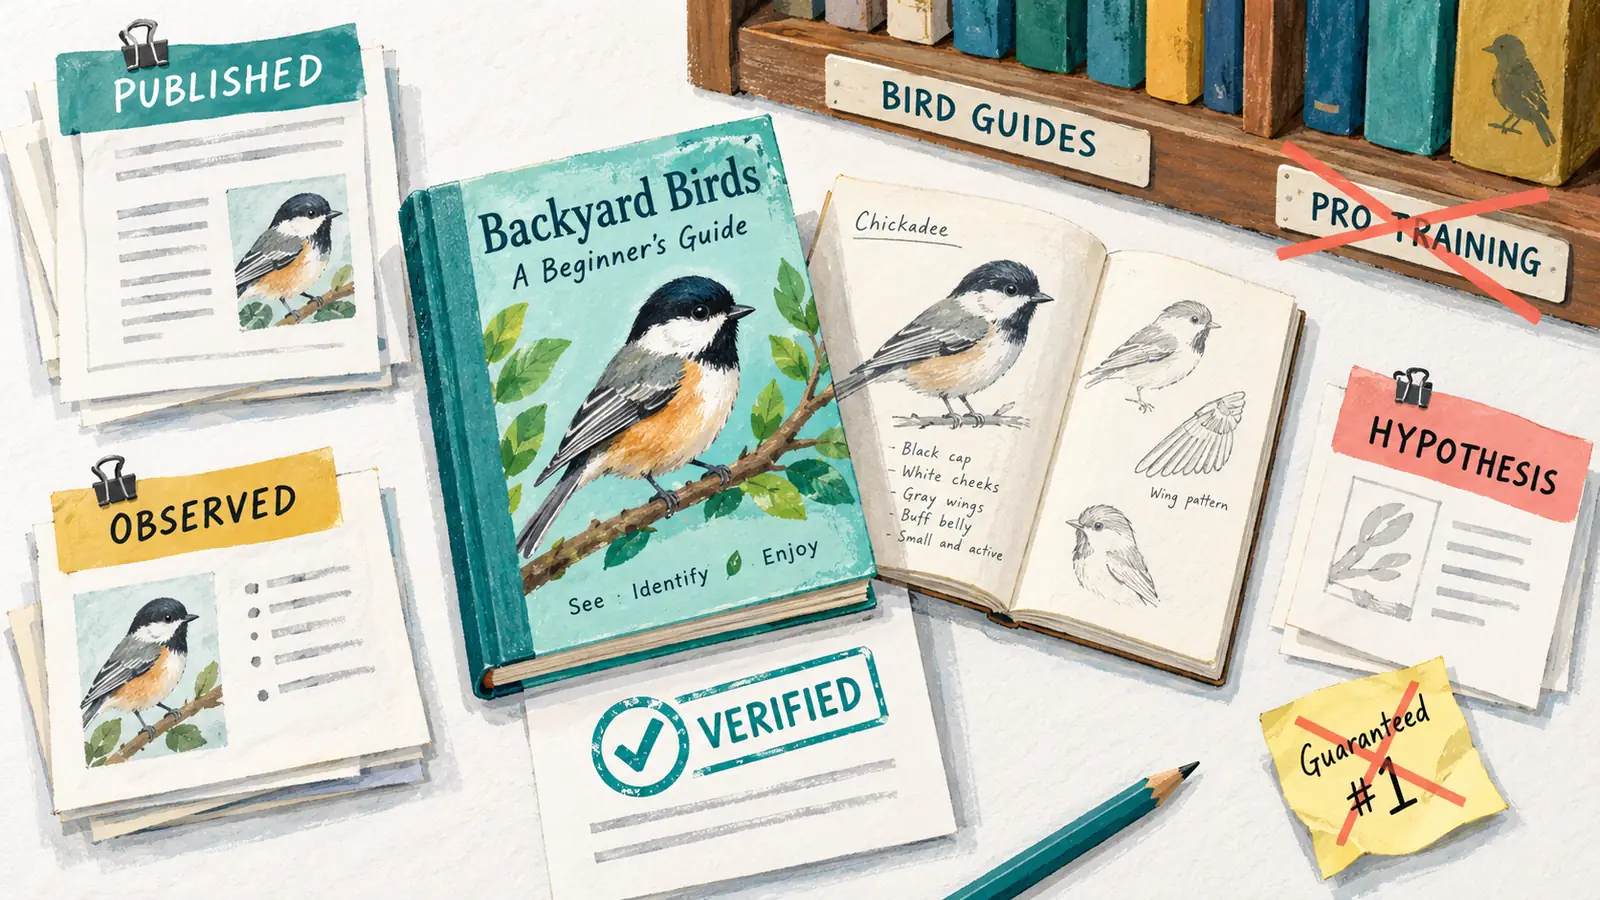
Label each claim as published guidance, a scoped observation or an untested hypothesis. A documented influence has no implied numerical weight; a before-and-after correlation does not establish a universal rule.
Do not score the unknown
"The description obscures the audience" is an inspectable publishing problem. "Description quality contributes 15% of ranking" is a numerical claim requiring evidence that the public guidance does not provide.
The register below is an evidence inventory, not a ranking formula or a claim that these are Amazon's only inputs. Use the systems explanation to distinguish publication, storefront observations and outcome reports.
Read the ranking evidence register
KDP's search guidance names sales history, availability, time listed and popularity. Its keyword guidance also relates relevant keywords and BSR to search placement. None of these statements supplies numerical weights or a guaranteed position.
| Topic | Evidence status and useful action | Do not infer |
|---|---|---|
| Sales history | Named search influence; inspect scoped reported outcomes | A fixed number of purchases for a target query position |
| Availability | Named search influence; verify the intended edition and market | Availability proves every relevant query will show the book |
| Time listed and popularity | Named influences; record publication context without inventing a score | A guaranteed launch window or private popularity formula |
| Keywords and BSR | Named in keyword/search guidance; inspect relevance and the correct rank scope | A universal formula linking a field or rank to query position |
| Categories | Published classification rules; choose a relevant shelf | An unrelated small category improves the right readership |
| Clicks and presentation | Measured interactions or editorial hypotheses, depending on the data | A disclosed organic click-to-rank weight |
| Reviews and reader feedback | Reader evidence; inspect specific expectations and verified defects | A review quota guaranteeing first-page placement |
Classification is a rule, not a shortcut
KDP's metadata rules require truthful fields and relevant categories. Correcting a misleading shelf can be necessary regardless of whether a short rank comparison improves. Compliance should not depend on a speculative commercial benefit.
For detailed operations, use the keyword strategy and the category decision workflow. Neither is a substitute for a manuscript that actually serves the chosen reader.
Choose the exact outcome before naming a cause
Write down whether the problem concerns availability, a specific query, a category-list position or retained earnings. The required evidence changes with the question. A public rank is not a count of impressions, and retail sales value is not automatically an author's retained amount.
Sales-rank documentation distinguishes relative activity and format/list scope. Keep a query-specific position separate. A category rank can move while your own activity stays similar because the comparison set is also changing.
Use a precise baseline statement
For an edition-level check, save the identifier and market. For a query, add department, filters, date and inspected range. For a category, record the actual displayed list label and free/paid state where applicable. For a cost review, state the report and retained-value assumptions.
Use the measurement guide to organize these fields. If a metric cannot answer the question, do not compensate by giving it more decimal places.
Prioritize repairs without pretending to know algorithm weights
Prioritize verified failures, truthful representation and affordable effort. Repair a broken edition path before testing a speculative phrase. This is a work order, not a ranking formula.
| Finding | Proportionate next action | Evidence to confirm |
|---|---|---|
| Verified publishing discrepancy | Resolve the correct edition or live-state problem | Intended offer accessible in the relevant store |
| Inaccurate promise or classification | Correct the truthful representation | Fields and manuscript agree |
| Plausible reader-experience mismatch | Inspect the sample and make one justified correction | Observed problem actually repaired |
| Uncertain promotional opportunity | Run a bounded genuine introduction if affordable | Scoped outcomes, costs and remaining uncertainty |
Keep a necessary correction even if rank is noisy
Correct an unsupported claim or broken file because it is wrong; measure commercial effects separately. An attractive competition score cannot make an absent topic fit the manuscript.
Audit a fictional book from findings to action
Backyard Birds is an invented illustrated guide for adult beginners identifying common birds. It is not a professional field-survey manual or a children's activity book. Suppose its description is vague, its sample is readable and its edition is directly available.
Finding one: the topic query is not observed
Record the inspected range and query context. A professional-training query does not fit this beginner guide. Reject it rather than add a misleading phrase.
Finding two: the description hides the intended reader
Original correction, only if accurate: an illustrated introduction for adults identifying common backyard birds through visible features and short observation exercises. It is not professional field-survey training.
Save the earlier version and rationale. Follow the description rules: no testimonial quotations, review requests or keyword-tag lists. A clearer description is a correction, not proof of future sales.
Finding three: a newsletter opportunity is untested
Check audience fit, actual deliverable and cost before booking. The fact that the cover is attractive or a query appears relevant does not establish that this placement will reach suitable buyers. Define an affordable stopping rule and the decision the test should inform.
Choose measurements that could change the decision
Use KDP Reports for its scoped activity and earnings views. Use an explicit query observation for search placement and campaign data for the campaign. Do not reconstruct organic CTR from total orders and a screenshot.
For a discretionary edit, record one change where practical, verify its live state and note concurrent events. When several necessary repairs happen together, call it a combined intervention. A before-and-after difference does not isolate each repair's causal effect.
Keep a useful unknown visible
It is acceptable to conclude that reader fit is clearer while commercial lift remains unknown. That is more useful than manufacturing a percentage improvement from incomparable rank numbers. Distinguish measured outcomes, estimates, models and missing data throughout the review.
Use the sales guide, the click guide and the review guide for the specific evidence you are examining.
Evaluate a tool or guarantee by its method
Ask where a number comes from, which population it covers and what is estimated. Use the BSR-to-sales audit for conversion claims. The BSR Calculator exposes scenario assumptions, not verified competitor demand.
Require a defined outcome and a falsifiable claim
Ask an "algorithm optimization" service for its actual deliverable. A metadata audit is not a guaranteed position. Do not use scripted engagement or artificial transactions; KDP's ranking guidance warns against manipulative purchasing or borrowing activity.
Do not infer that clicks or reviews never matter merely because no public numerical weight is available. The defensible boundary is that the proposed weight or guaranteed effect has not been established by the cited evidence.
Write a decision memo instead of a ranking score
Summarize the observation, evidence status, action, confirmation and next review. Keep the memo short enough to compare with the actual result later. Name the uncertainty that would make you change the plan.
The fictional bird guide is available and its sample is readable. Reject the professional-training query, clarify the beginner audience and verify the live description before considering a bounded promotion.
Choose the next task, not every task
Use the ranking workflow map for the relevant specialist guide, or the discovery plan when the audience is still undefined. A useful factor audit ends with a justified publishing decision, not a new invented algorithm.
Explore the KDP discoverability guides to connect this question with keywords, categories and ranking evidence.
Sources and scope
Official references checked on 16 October 2026. Book, artwork, findings and copy are fictional. Evidence labels and repair order are editorial frameworks, not Amazon coefficients. No live volume, private weights, guaranteed position or causal lift is claimed.
Frequently asked questions
Which Amazon book search influences are publicly named?
KDP names sales history, availability, time listed and popularity. Its keyword guidance also names relevant keywords and BSR in search placement. These statements do not disclose numerical weights or guaranteed positions.
Should I assign percentages to ranking factors?
Not without evidence supporting those weights. Use evidence labels and operational priorities rather than presenting an invented score as Amazon's formula.
Are keywords and categories permission to target any popular topic?
No. They must accurately describe the book. Reject a query or shelf the manuscript does not support, regardless of an attractive competition estimate.
What should I repair first?
Start with verified publishing discrepancies and inaccurate representation. Then inspect plausible reader-experience problems and consider affordable tests. This is an operational repair order, not a hidden ranking-weight model.
Does an undisclosed click or review weight mean no possible effect?
No. Lack of a published numerical weight does not establish that interactions or feedback never matter. It limits the ranking claim you can support from the available evidence.
How should I evaluate a ranking tool?
Ask where its data comes from, what population and period it covers, which values are estimates and how its method could be checked. A proprietary score is not automatically Amazon's own score.